Futa Waseda
Futa Waseda
Home
Projects
Publications
Contact
CV
EN
日本語
Closer Look at the Transferability of Adversarial Examples: How They Fool Different Models Differently
Futa Waseda
,
Sosuke Nishikawa
,
Trung-Nghia Le
,
Huy H. Nguyen
,
Isao Echizen
January 2023
Paper
Video
Poster
DOI
Cite
TL;DR
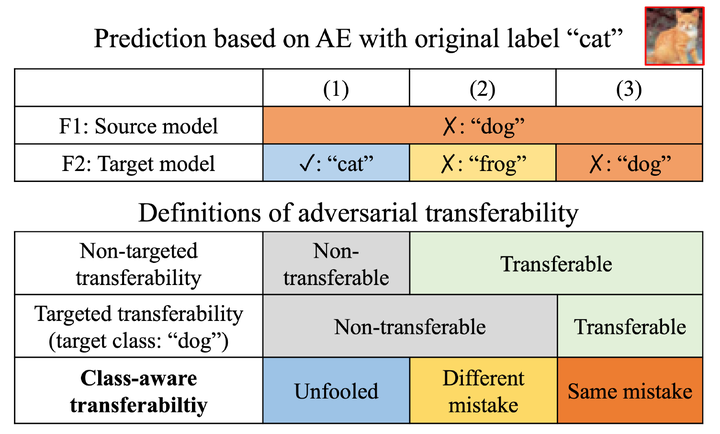
Transferred attacks can cause different mistakes
: Distinguishes whether source and target models predict the same wrong class.
Similar models can still disagree under attack
: Different mistakes occur even between similar models and across perturbation sizes.
Non-robust features explain class-aware transfer
: Models can use the same adversarial features differently, producing different wrong labels.
Type
Conference paper
Publication
Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision. 2023.
Presentation Video
Presentation Poster
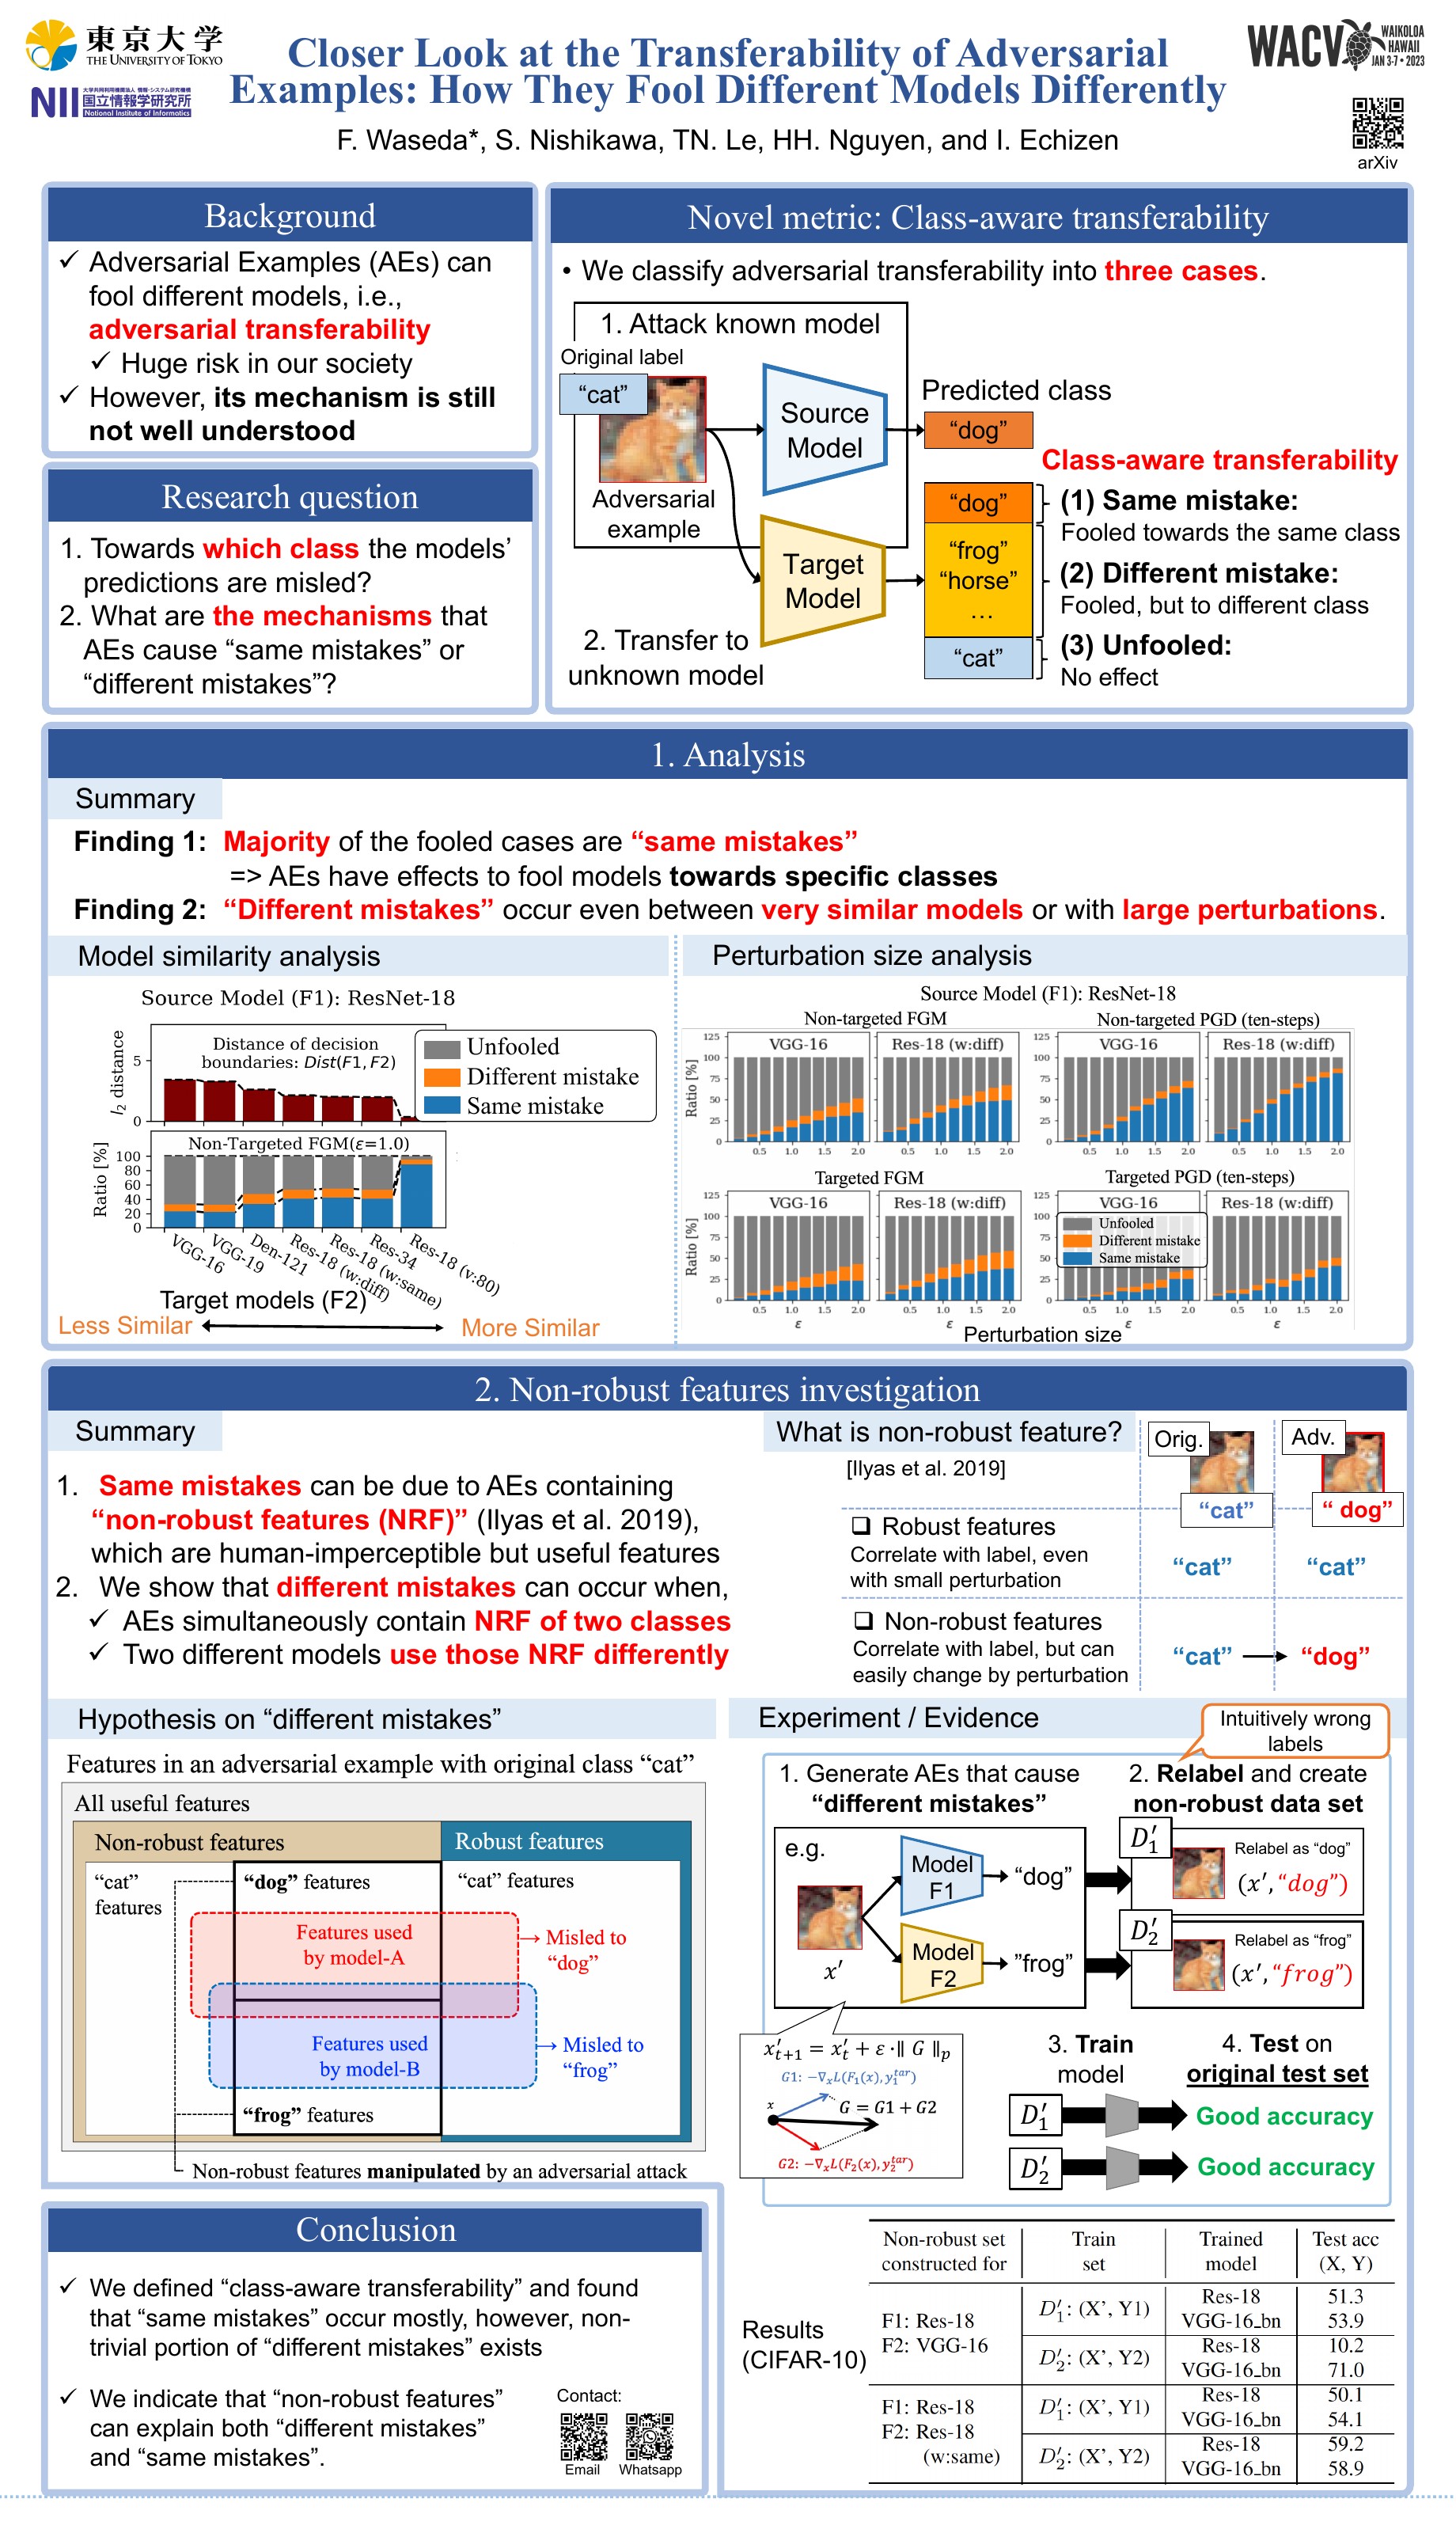
Open poster
Recent
Futa Waseda
Project Assistant Professor
Related
【ICIP 2024】Defending Against Physical Adversarial Patch Attacks on Infrared Human Detection
【SMC 2026】Semantic Color Naturalness Breaker: Preventing Illegitimate Colorization via Content-Aware Color Priors
【APSIPA ASC 2025】Uncolorable Examples: Preventing Unauthorized AI Colorization via Perception-Aware Chroma-Restrictive Perturbation
【WACV 2026】Multimodal Adversarial Defense for Vision-Language Models by Leveraging One-To-Many Relationships
【ACM MM 2025】Quality Text, Robust Vision: The Role of Language in Enhancing Visual Robustness of Vision-Language Models
Cite
×