Futa Waseda
Futa Waseda
ホーム
研究テーマ
論文一覧
お問い合わせ
CV
EN
日本語
Text-Printed Image: Bridging the Image-Text Modality Gap for Text-centric Training of Large Vision-Language Models
Shojiro Yamabe
,
Futa Waseda
,
Daiki Shiono
,
Tsubasa Takahashi
June 2026
Paper
DOI
引用
TL;DR
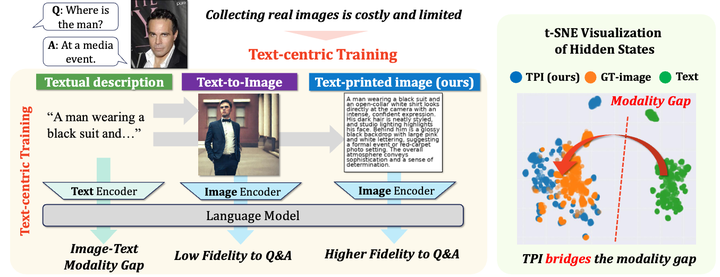
文字を描画した画像で低コストにVLMを学習
:TPIは白い画像にテキスト説明を直接描画。
文字の描画で画像と言語のギャップを縮小
:実画像を収集せずに視覚入力の学習データを生成。
拡散モデルによる学習画像を上回る性能
:意味の正確さを保ち、複数のベンチマークで改善。
タイプ
Conference paper
収録
CVPR 2026
Recent
Futa Waseda
特任助教
関連項目
【ECCV 2026】Read or Ignore? A Unified Benchmark for Typographic-Attack Robustness and Text Recognition in Vision-Language Models
【ICLR 2026】Understanding Sensitivity of Differential Attention through the Lens of Adversarial Robustness
【ACL 2025 Main】MergePrint: Merge-Resistant Fingerprints for Robust Black-box Ownership Verification of Large Language Models
【SMC 2026】Semantic Color Naturalness Breaker: Preventing Illegitimate Colorization via Content-Aware Color Priors
【APSIPA ASC 2025】Uncolorable Examples: Preventing Unauthorized AI Colorization via Perception-Aware Chroma-Restrictive Perturbation
引用
×